Created a list of around 100 books that had major impact on me over the last two decades. These are also the books that I've re-read several times. buff.ly/2xaaDLd

 Open web. Clear feed.

Angel Investor | Global R&D Leader - Cloud | Data | AI/ML | RF |Semicon | EDA | S/w Architecture. Itinerant. Distance Runner.
Created a list of around 100 books that had major impact on me over the last two decades. These are also the books that I've re-read several times. buff.ly/2xaaDLd

a senior engineer just explained why the Microsoft outage took 15 hours and why AI won't replace programmers anytime soon.


Every resource above, free: Karpathy, Neural Networks: Zero to Hero karpathy.ai/zero-to-hero.htm… Jay Alammar, The Illustrated Transformer jalammar.github.io/illustrat… OpenAI tiktoken github.com/openai/tiktoken OpenAI structured outputs guide platform.openai.com/docs/gui… Anthropic prompt caching docs docs.anthropic.com/en/docs/b… Hugging Face LLM Course huggingface.co/learn/llm-cou… pgvector github.com/pgvector/pgvector Hamel Husain, Your AI Product Needs Evals hamel.dev/blog/posts/evals/ Ragas github.com/explodinggradient… Anthropic, Building effective agents anthropic.com/engineering/bu… Lilian Weng, LLM Powered Autonomous Agents lilianweng.github.io/posts/2… Model Context Protocol modelcontextprotocol.io/ Full Stack Deep Learning, LLM Bootcamp fullstackdeeplearning.com/ll… OpenAI Cookbook (worked examples for weeks 3-10) cookbook.openai.com/
AI engineer roadmap for backend developers If you can ship an API, a queue and a database, you're closer to an AI engineering job than most people with an ML certificate. The model call is one line. Everything around it is backend work. Weeks 1-2: How LLMs actually work - Karpathy's "Neural Networks: Zero to Hero". Watch "Let's build GPT" and the tokenizer lecture - Jay Alammar's "The Illustrated Transformer" for the attention picture - Count tokens with OpenAI's tiktoken before you count dollars - Build: a CLI chat that streams replies and prints tokens and cost per turn Weeks 3-4: Call models like an engineer - Structured outputs with a JSON schema, then validate it anyway - Timeouts, retries with backoff, streaming, fallbacks to a second model - Prompt caching docs: what gets cached and why it cuts latency and cost - Hugging Face LLM Course, first chapters, for the vocabulary - Build: an extraction API. PDF invoice in, validated JSON out, with schema tests Weeks 5-6: Retrieval on Postgres - pgvector: embeddings inside the database you already run - Chunking, hybrid search (keyword + vector), re-ranking, citations - Build: Q&A over a real docs site that cites the exact chunk it used Weeks 7-8: Evals, the part every roadmap skips - Hamel Husain, "Your AI Product Needs Evals" - Ragas for retrieval metrics like faithfulness and context precision - Write 50 real test questions before you touch the prompt again - Build: an eval harness that runs in CI and fails the build when answers regress Weeks 9-10: Tools and agents - Anthropic, "Building effective agents". Start with simple workflows, add agents only when the task needs them - Lilian Weng, "LLM Powered Autonomous Agents" for the mental model - Model Context Protocol docs: expose one internal API as a tool - Build: an agent that turns a support message into a bug ticket, with a human approval step before anything is created Weeks 11-12: Production - Full Stack Deep Learning's LLM Bootcamp lectures (free) - Log every prompt and response, track cost per request, p95 latency and error rate - Rate limits, PII redaction, what happens when the provider is down - Build: ship one project behind auth with a dashboard, plus a one-page design doc How to use this: - 6-8 hours a week. Build first, read when you get stuck - Every build goes on GitHub with a README: problem, architecture, eval results, what broke - Skip fine-tuning until the end. Most product teams need retrieval and evals first - Pick builds that touch data you understand. Your own notes, your company's docs (with permission), public datasets - If a week takes two weeks, fine. Don't skip the build My take: Queues, caching, idempotency, observability. The skills you already have are the job. The people who get hired can show an eval report, not a certificate. Which week would you swap for your stack?


Matteo Vaccari claims that with agentic engineering we need to re-orient our testing strategy with broader-scope tests represented as data rather than code. martinfowler.com/articles/te…

Long-horizon agents can automate tasks that take days or weeks, but much can go wrong. Kiran Prakash explains how durable execution allows agents to recover. martinfowler.com/articles/du…


NYU Prof. Aswath Damodaran, the world's leading valuation expert and AI skeptic, on the ‘AI will triple GDP’ hype: “Real GDP growth has been lower globally over the last forty years than it was before PCs. All this stuff that claimed to make us more productive just redistributed wealth rather than make us all more wealthy.”
This is such a brilliant idea.
Weekend hack: HackerTube. I was annoyed with YouTube's recommendations so I had Claude filter down 43M comments over 20 years of HN to 6,454 videos that keep being recommended. *Significantly* better viewing experience, ~2 hours with Opus 5.5: hackertube.org/ - Excellent recs without any logins (state is kept in local browser session) - Thumbnail is a representative frame from middle of the video instead of the super duper A/B test hyper-optimized user uploads - Underlying data from the comment analysis as one zip file, point your Claude at it and ask for your own version - HackerTube Longs ✊ A bit more on the process: I use Claude Code (desktop app for Mac), Opus 5.5 on Medium effort as my default. I only talk to Claude and have it do everything, the only "manual work" I helped with in tandem was in the browser (reminiscent of MenuGen): 1) I had to create some kind of API key from Google Cloud UI to query YouTube for video metadata, 2) I booted up a VPS box for serving and 3) I bought the domain name. Once the box was up I gave Claude the IP and told it update, secure, harden, deploy and optimize the code, and it did the whole thing. Many awesome projects that would have normally taken weeks/months even can now be few-shotted for breakfast. What else are we not thinking of.


Very excited to share Genie 4, our incredible interactive world model, bringing together real-time physics, reasoning, and audio! Simulations within simulations, makes you wonder just how deep the rabbit hole goes... I have a feeling we will be finding out soon enough...
This is Genie 4, our most realistic and interactive world model yet. 🌐 Explore dynamic environments in real time to see how the scene responds, sounds, and how the people in it move, react, and speak.

What tasks should AI be trusted with, and when should humans remain involved? Designing those decision rights is one of the defining challenges of the AI era. Researchers at the MIT Center for Information Systems Research have developed a framework to help. Learn more: bit.ly/4zed20M


Last 3 overs of the epic knock of Virat Kohli in the Ind Vs Pak match, with scintillating commentary by the ausie commentator! 🔥 x.com/Melbourne__82/status/2…

Here's my updated review of each personal agent: 1. Grok Bot Pros: A team of bots is the easiest to understand. Free X access is amazing for research. Voice mode and the new Pages feature are great. Cons: Email feature doesn't really work. 2. Muse Pros: Free, best consumer UX, most meme-worthy avatar, and business calling is amazing. Cons: Muse Wonder is good but Opus/Astra is better. 3. Claude Duet Pros: Most proactive out of the box. Feels polished and simple to use. Arguably the best model behind it. Cons: Missing some features in research preview, like being able to drive its browser. 4. ChatGPT Dots Pros: Works inside ChatGPT, so it can drive all your cloud and local threads. Cons: Much better than at launch but still buggy. Voice mode is slow to connect. I've also tried Instinct and some of the other agents, but I don't want more than 4 at a time connected to my email. 📌 Don't miss my full Claude Duet review here for everything that it can do: youtu.be/D-pz8L1orVI
Claude Duet, Anthropic’s 24/7 personal agent, is finally here. I had early access and here’s my new video with my honest take on: → Why I think it's the most proactive agent → Why Artifacts could be its secret sauce → How it stacks up to Grok Bot, Muse, and Dots Duet is in research preview and I’m sure will improve a lot over time. 📌 Watch now: youtu.be/D-pz8L1orVI x.com/claudeai/status/211298…

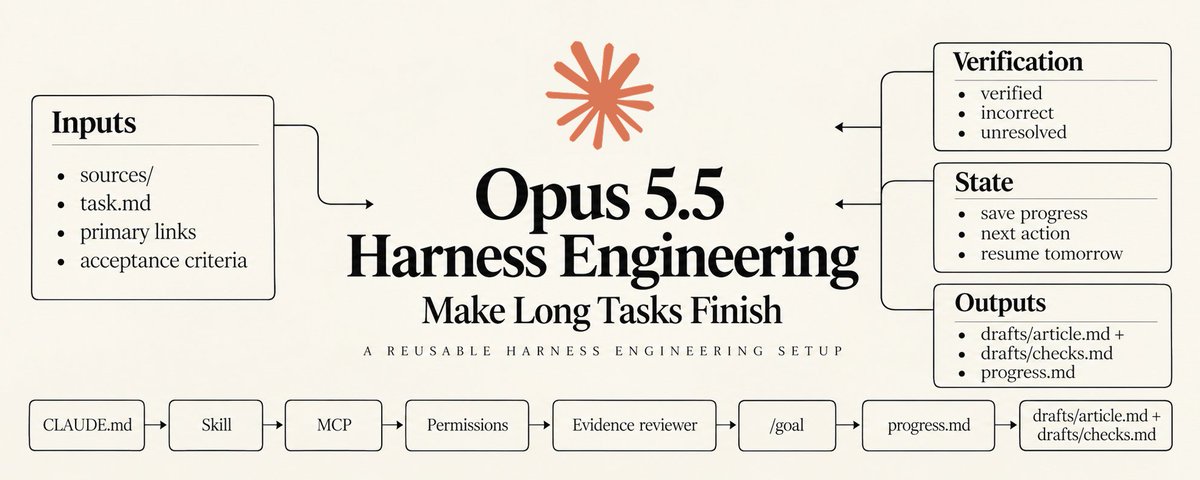
Anthropic hired this engineer at $350K–$850K a year because he knows how to build harnesses for multi-agent systems In a 12-minute workshop, he shows exactly how to build one from scratch AI → Agents → Harness → Loops → Graphs step 1 → start with the Claude Agent → the harness handles loops, context, and sandboxing step 2 → separate the brain from the hands → reasoning in one place, tools in a sandbox, 60% faster to first token step 3 → run it server-side and log every step → close your laptop and it keeps running, crashes resume from the log step 4 → make failure cheap → retry dead sandboxes and replay lost context instead of starting over step 5 → turn yesterday's logs into new memory and skills → the harness wakes up smarter Anthropic calls this "dreaming" Most people spend weeks building this by hand You don't have to Bookmark and watch it Then read the full Opus 5.5 harness engineering guide below ↓
Stop letting unfinished Opus 5.5 runs eat your budget Set up the harness before your next long task Save progress, verify results, reuse the workflow The full 7-layer setup below ↓

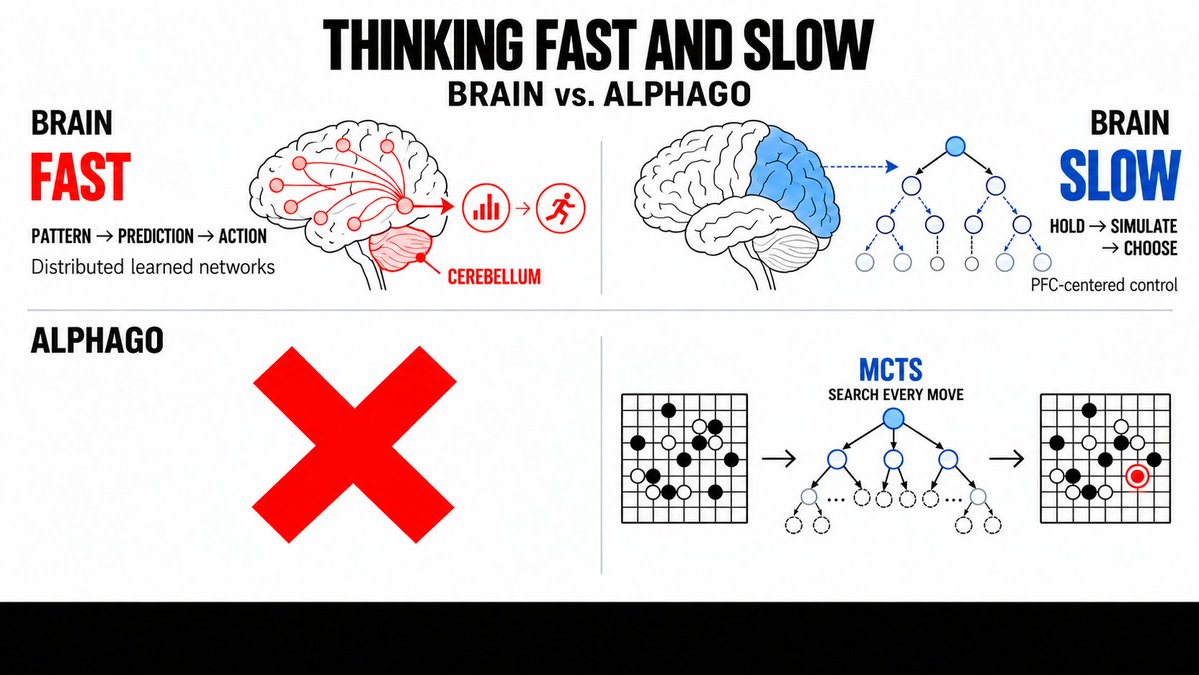
Remember Kahneman's Thinking, Fast and Slow? The brain decides when to rely on learned patterns (sys1-fast/Cerebellum + distr. networks) vs. deliberate thinking (sys2-slow/Prefrontal Cortex). Energy and compute constraints necessitates efficiency. Where is the System 1 for RL?