←
Sarah Eslami618 posts
Sarah Eslami avatar

Sarah Eslami

@ESL_Sarah

Search @perplexity_ai | prev @JinaAI_ @sap @HPI_DE | Multimodal LLMs, embeddings

◷ Joined November 2015▧ 11 Photos and videos
Slack avatar
⟳ Sarah Eslami retweeted
Slack@SlackHQ·Nov 16

It started with a few hundred lines of code. Now @perplexity_ai's AI agent, Computer, can connect information across your tools, get other AI models to challenge your thinking, and even kick off a code change. All with a simple mention in Slack.

2:45
Denis Yarats avatar
⟳ Sarah Eslami retweeted
Denis Yarats@denisyarats·Nov 12

we are launching our latest decision models, pplx-decider-v1.3 and pplx-decider-flash-v1.3. for this release we prioritized robustness, so the models can support a wide variety of use cases. we also added locate, a new feature that extracts spans from the input conditioned on instructions (e.g., NER, PII detection, extractive QA). finally, we wrote a very detailed blog post on how we train, evaluate, and use the decision models internally: perplexity.ai/hub/blog/perpl…

Post attachment

We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models. v1.3 adds locate, a new feature that extracts spans based on type or instructions. Now available in our Decisions API, @huggingface, and @OpenRouter. perplexity.ai/hub/blog/perpl…

0:16
Bo avatar
⟳ Sarah Eslami retweeted
Bo@bo_wangbo·Nov 12

We introduced locate in decider v1.3. Now decision model can act as a NER, PII and perform extractive QA tasks. We also wrote a blogpost demonstrating the training, evaluation and inspiring use cases of decider:

We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models. v1.3 adds locate, a new feature that extracts spans based on type or instructions. Now available in our Decisions API, @huggingface, and @OpenRouter. perplexity.ai/hub/blog/perpl…

0:16
Antoine Chaffin avatar
⟳ Sarah Eslami retweeted
Antoine Chaffin@antoine_chaffin·Nov 12

We are releasing the new version of our Decider models It comes with improved performance and robustness, a new locate feature to extract spans from inputs (e.g, PII), a thorough blog post and one free week for both models on Open Router!

We're rolling out pplx-decider-v1.3 and pplx-decider-flash-v1.3, the latest version of our open-weight decision models. v1.3 adds locate, a new feature that extracts spans based on type or instructions. Now available in our Decisions API, @huggingface, and @OpenRouter. perplexity.ai/hub/blog/perpl…

0:16
Perplexity avatar
⟳ Sarah Eslami retweeted
Perplexity@perplexity_ai·Nov 5

Introducing teammates. Teammates work for you. They take on jobs, and work proactively using your Computer tasks, skills, memory, and tools. Teammates collaborate with other teammates and can message coworkers in Slack. Available now for Max subscribers on the web.

1:11
Aravind Srinivas avatar
⟳ Sarah Eslami retweeted
Aravind Srinivas@AravSrinivas·Nov 5

Today, we're launching Perplexity Teammates. They are personal agents for work. And change the paradigm from writing prompts in a session to giving high-level goals. Rolling out to Max users on the web today. Native apps (mobile, desktop) coming soon.

1:11
Denis Bykov avatar
⟳ Sarah Eslami retweeted
Denis Bykov@denis_bykov·Nov 5

Okay, teammates are really cool, but we couldn't wait to share our latest research capability upgrades. Meet the new Agent API update: stronger and cheaper! Greetings from the Search and API teams :) P.S. Yes, with multi-agents: check out the new ultra level!

Post attachment

Every Agent API effort level now costs less with the same or higher research quality. Effort levels are bundled agent configurations, optimized for specific tasks. A new ultra level is available for the most demanding, long-running requests. pplx.ai/effort-levels

turbopuffer avatar
⟳ Sarah Eslami retweeted
turbopuffer@turbopuffer·Nov 3

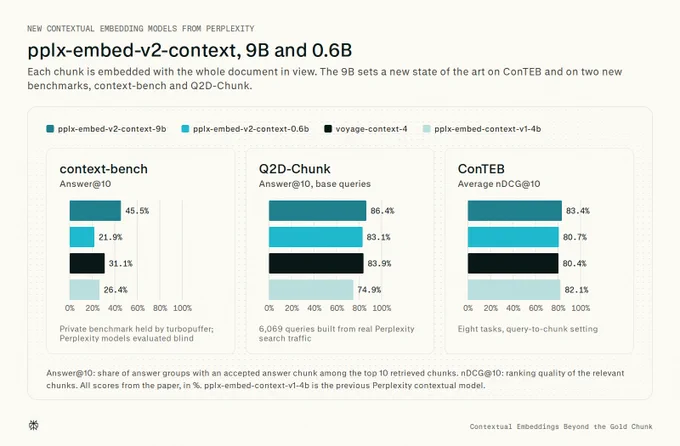
contextual embedding improves relevance by encoding the context of a full document into each chunk's embedding we worked with @perplexity_ai to iteratively evaluate their model checkpoints against our private benchmark, resulting in a state-of-the-art contextual embedding model

Introducing pplx-embed-v2-context: open-weight vision-language embedding models in 9B and 0.6B. Both return one int8 vector per document, or one per chunk that sees the whole document. Read the paper, written with @turbopuffer: arxiv.org/abs/2610.38854

Post attachment
tomaarsen avatar
⟳ Sarah Eslami retweeted
tomaarsen@tomaarsen·Nov 3

🔎 @perplexity_ai 's pplx-embed-v2-context models let you retrieve small chunks with the surrounding document still in view. 0.6B & 9B, text + images, and you can index with 9B while serving queries with 0.6B. A thread on how they work 🧵

Introducing pplx-embed-v2-context: open-weight vision-language embedding models in 9B and 0.6B. Both return one int8 vector per document, or one per chunk that sees the whole document. Read the paper, written with @turbopuffer: arxiv.org/abs/2610.38854

Post attachment
Sarah Eslami avatar
Sarah Eslami@ESL_Sarah·Nov 3

Find more details in our tech report: arxiv.org/abs/2610.38854 Joint work with Markus Krimmel, @n0riskn0r3ward, @antoine_chaffin, Louis Milliken, @MaxSchall1, @jongolde, Ekaterina Glazkova, @bo_wangbo and @denis_bykov! 🙌

Sarah Eslami avatar
Sarah Eslami@ESL_Sarah·Nov 3

We also investigate how the model performs in non-contextual settings for document retrieval, treating entire documents as a single chunk.

Sarah Eslami avatar
Sarah Eslami@ESL_Sarah·Nov 3

Official now! 🚀 Excited to share the outcome of a project I'm particularly excited about. We're introducing a SOTA int8-quantized contextual embedding model, a public leaderboard for chunk retrieval evaluations, and exploring our model's potential for visual document retrieval.

Introducing pplx-embed-v2-context: open-weight vision-language embedding models in 9B and 0.6B. Both return one int8 vector per document, or one per chunk that sees the whole document. Read the paper, written with @turbopuffer: arxiv.org/abs/2610.38854

Post attachment
Antoine Chaffin avatar
⟳ Sarah Eslami retweeted
Antoine Chaffin@antoine_chaffin·Nov 2

Back then, we released a preview of our new contextual models, offer an answer to the chunking problem Today we’re releasing a new 0.6B model sharing the embedding space of the 9B, a new public benchmark, as well as strong vision results And it comes with a thorough tech report

Post attachment

Introducing pplx-embed-v2-context: open-weight vision-language embedding models in 9B and 0.6B. Both return one int8 vector per document, or one per chunk that sees the whole document. Read the paper, written with @turbopuffer: arxiv.org/abs/2610.38854

Post attachment
Antoine Chaffin avatar
⟳ Sarah Eslami retweeted
Antoine Chaffin@antoine_chaffin·Oct 22

We've released a technical report on the released late interaction models It's purposely kept short, simple and direct, because most of the recipe is not new (shared space is not really new as well, but pretty cool for ColBERT still) There are still a lot of technical information if you are interested beyond the BP We are preparing much more thorough papers for things where we did really bring a lot of novelty, pretty sure you'll enjoy those! arxiv.org/pdf/2610.29523v1

dinos@din0s_Oct 22

gm chat 👑

Post attachment
Bo avatar
⟳ Sarah Eslami retweeted
Bo@bo_wangbo·Oct 18

we at Perplexity contributed a little during mid-training, more coming soon:

Post attachment

Meet NVIDIA Nemotron 3.5 Super VL Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents. 120B total parameters with 12B active 🧵

1:20