📢 #scholarGPT now can perform complex filtering operations like selecting a specific year 📅, making research even more efficient! 💪 Build with self-query from @langchain
Sign up on the waitlist to be the first to try it out mailchi.mp/d8b3dbb881ae/scho…! 🚀✨ #ChatGPT#Research🧑💻
One fun aspect of our latest blog post: You can change its reasoning effort.
Drag the slider and the post rewrites itself word by word, from a 12-minute read at high down to 2 minutes at none.
Kolibri can reason at four efforts: none, low, medium, and high. Our SFT training traces didn't have effort labels, so we had to label them post-hoc.
A new blog post by @L_Salewski explains how we did this, with interactive figures 🧵
The Kolibri tech report is now on arXiv: arxiv.org/abs/2610.31945. If you haven't read it yet, give it a read - it covers all steps on how to build a modern LLM.
During its development, Kolibri surprised us in ways we didn't expect with reward hacking & escaping sandboxes. We were a little proud but also increased our sandbox isolation
For an 80B-A3B model, it is unexpected. All the details are in "Lessons learned" section in tech report
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
We started the year with the conviction that Europe needs its own sovereign AI. Built in Germany from scratch and on infrastructure in Europe specifically for our customers.
This weekend, we released Kolibri.
Meet the team behind it 🧵
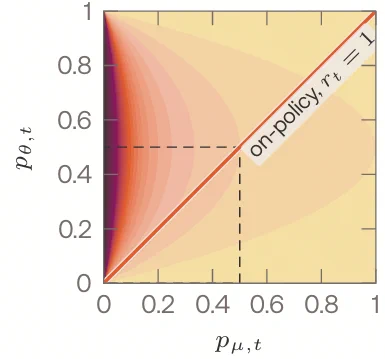
My favorite reinforcement learning plot from our Kolibri report: Inference v.s. training log probs, background is the logit gradient norm of importance-sampled Reinforce. Numerically unstable for small inference log-probs, but you can do exact token-level gradient clipping in RL.
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
Check section 3.1.4.1 of our tech report (aleph-alpha.com/downloads/te…) for more details. It also has many more details, so certainly worth a read on how to train a model end-2-end!
This adds a small bias: a step's microbatches are no longer a plain random draw. In our runs the wall-clock gain won by a wide margin: median throughput per GPU went from 8,610 to 15,850 tokens/s on 64 B300s, +84%, same data, model and kernels.
The trick: Every GPU fills a buffer of packed sequences and sorts it by attention cost. Then all GPUs draw from their buffers in the same seeded random order. Equal-size buffers from the same distribution sort alike, so the i-th draw costs about the same everywhere. Nobody waits.
2: Profiling the run, some GPUs idled a lot, but random ones each step, and tokens/s varied a lot. With document masking the attention cost of a packed sequence is Σ|d|², so equal-length sequences cost unequal work, and FSDP makes every GPU wait for the slowest at each sync.
Here are two neat speed tricks we found while SFT'ing Kolibri 🧵
1: We use standard Next-k-fit online bin packing with document masking maximises useful tokens per sequence. Whats easy to miss: less padding means a larger effective batchsize, so the learning rate can go up.
In post-training, we taught Kolibri to think and answer in both English and German consistently across SFT and RL alike. We generated large amounts of synthetic data to control how Kolibri answers and trained with RL on more than 1.2 million tasks, including ones built around our customer needs, and ones to teach it to say “I don’t know” when the context is insufficient.
Here is one interesting detail from our post-training:
Kolibri scores above 90% on AIME 2025 and AIME 2026 just after SFT. We also evaluated on an internal AIME 2026-like eval with new IID samples and got even better results. For math, RL was just the finishing touch than.
In post-training, we taught Kolibri to think and answer in both English and German consistently across SFT and RL alike. We generated large amounts of synthetic data to control how Kolibri answers and trained with RL on more than 1.2 million tasks, including ones built around our customer needs, and ones to teach it to say “I don’t know” when the context is insufficient.
Big congrats to my friends at Aleph. Glad I was still around when this team formed and got to see how much work went into building it end to end.
kolibri.constructlabs.com
We will offer inference for free for the next ~48 hours.
Hit me up if you are interested in bringing this into production or post-training it.
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
Dear @Aleph__Alpha team - thank you for making Kolibri-1 open.
We care deeply about sovereign AI, and launching it on German Unity Day makes today feel especially fitting.
As a small gesture of support, we’ve hosted and made Kolibri-1 free for anyone to try for the next few days.
No GPU. No setup. Just try it.
tesseracted.com/kolibri-1-ch…
Open Models move us all forward.
We’re rooting for you. 🇩🇪
Tesseracted Labs GmbH.
tesseracted.com#alephalpha#openweightmodels