←
J.Nathan Yan258 posts
J.Nathan Yan avatar

J.Nathan Yan

@NathanYan2012

Research Scientist @GoogleDeepMind. Ph.D. from @CornellCIS/@cornell_tech. I bake my own opinions.

◷ Joined July 2014▧ 1 Photos and videos
Melvin Johnson avatar
⟳ J.Nathan Yan retweeted
Melvin Johnson@melvinjohnsonp·Nov 12

Today we’re rolling out Gemini 4 Hydrogen! While teams rely on Gemini 4 Carbon and Gemini 4 Argon for deep architectural judgment and untangling subtle bugs, you also need a fast, disciplined model for writing code, running tests, and verifying changes. Hydrogen stands on its own for everyday work, surpassing Argon on the Artificial Analysis Intelligence Index at its default thinking level (51 vs. 50, reaching 54 at xhigh)....or pairs with Carbon as the high-efficiency execution engine in multi-model workflows. It is at the pareto for speed vs quality and has been delivering fast frontier intelligence for our teams.

Post attachment
Google DeepMind avatar
⟳ J.Nathan Yan retweeted
Google DeepMind@GoogleDeepMind·Oct 28

Gemini 4 Carbon is our next frontier model. It’s state-of-the-art across cybersecurity and long-horizon capabilities.

Post attachment
J.Nathan Yan avatar
J.Nathan Yan@NathanYan2012·Oct 27

Very nice post!!!

how much can models remember? there’s a neat perspective on neural networks that deserves to be more widely known here’s how you could have invented every layer of the transformer from memory (1/n) from my new blog post!

Google DeepMind avatar
⟳ J.Nathan Yan retweeted
Google DeepMind@GoogleDeepMind·Sep 30

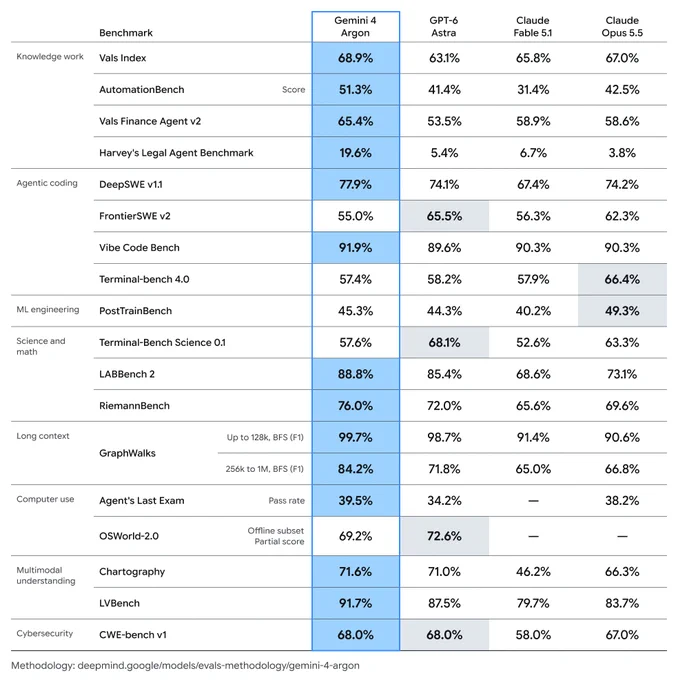
Introducing Gemini 4 Argon – our new frontier model. It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.

Post attachment
J.Nathan Yan avatar
J.Nathan Yan@NathanYan2012·Jun 24

wowowowo gooooo Jack!!!

finally sharing what i've been up to! left phd end of 2025 and co-founded Engram. there are a few startups in SF right making very different bets on the right way to train AI models. this is ours: people want models that learn over time, remember details, adapt and interact like a person would everyone gets a model. your model updates ~every minute. this is the world we're building. :)

Sasha Rush avatar
⟳ J.Nathan Yan retweeted
Sasha Rush@srush_nlp·Mar 25

It's really neat to see all the interest in the Composer 2 technical report, from training to kernel design to inference. If you have any questions about why we did things, feel free to ask. I'll run around the office and bug people.

We're releasing a technical report describing how Composer 2 was trained.

Post attachment
Jack Morris avatar
⟳ J.Nathan Yan retweeted
Jack Morris@jxmnop·14 May 2025

# Embeddings are underrated (2024) just a really excellent piece of technical writing.

Post attachment
Jiatao Gu avatar
⟳ J.Nathan Yan retweeted
Jiatao Gu@thoma_gu·22 Apr 2025

I will be attending #ICLR2025 in person during Apr 24-28, and presenting our research: DART: Denoising Autoregressive Transformer 📌Fri 25 Apr 3 p.m. +08 — 5:30 p.m. +08 This is my first time visiting Singapore, and I am looking forward to chatting with old and new friends!

Jiatao Gu@thoma_gu12 Oct 2024

🚀Excited to introduce our recent work @ AppleMLR -- DART: Denoising AutoRegressive Transformer for Scalable Text-to-Image Generation! A transformer-based model that unifies Autoregressive and Diffusion with a non-Markovian diffusion framework: 🔗 arxiv.org/abs/2410.08159 (1/n)

Post attachment
Karan Dalal avatar
⟳ J.Nathan Yan retweeted
Karan Dalal@karansdalal·7 Apr 2025

Today, we're releasing a new paper – One-Minute Video Generation with Test-Time Training. We add TTT layers to a pre-trained Transformer and fine-tune it to generate one-minute Tom and Jerry cartoons with strong temporal consistency. Every video below is produced directly by the model in a single shot, without editing, stitching, or post-processing. Every story is newly created. Demos: test-time-training.github.io… Paper: test-time-training.github.io…

1:03
Sasha Rush avatar
⟳ J.Nathan Yan retweeted
Sasha Rush@srush_nlp·20 Mar 2025

Some personal news: I recently joined Cursor. Cursor is a small, ambitious team, and they’ve created my favorite AI systems. We’re now building frontier RL models at scale in real-world coding environments. Excited for how good coding is going to be.

0:19
Hamish Ivison avatar
⟳ J.Nathan Yan retweeted
Hamish Ivison@hamishivi·4 Mar 2025

How well do data-selection methods work for instruction-tuning at scale? Turns out, when you look at large, varied data pools, lots of recent methods lag behind simple baselines, and a simple embedding-based method (RDS) does best! More below ⬇️ (1/8)

Post attachment
Songlin Yang avatar
⟳ J.Nathan Yan retweeted
Songlin Yang@SonglinYang4·25 Feb 2025

I've uploaded the latest slides & beamer source code to github.com/sustcsonglin/line…. Hopefully this repository will help train an LLM that generates Beamer slides better than I do :)

Sasha Rush@srush_nlp24 Feb 2025

Linear Attention and Beyond: Interactive Tutorial with Songlin Yang (@SonglinYang4 MIT/Flash Linear Attention) I didn’t follow some of the recent results, so I zoomed Songlin and she explained it all to me for two hours 😂 youtu.be/d0HJvGSWw8A

Songlin Yang avatar
⟳ J.Nathan Yan retweeted
Songlin Yang@SonglinYang4·21 Feb 2025

Introducing the first open-source implementation of native sparse attention: github.com/fla-org/native-sp…. Give it a spin and cook your NSA model! 🐳🐳🐳