←
Sawyer Bowerman70 posts
Sawyer Bowerman avatar

Sawyer Bowerman

@_soyr_

AI @ Red Hat

◷ Joined February 2026▧ 1 Photos and videos
Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Oct 20

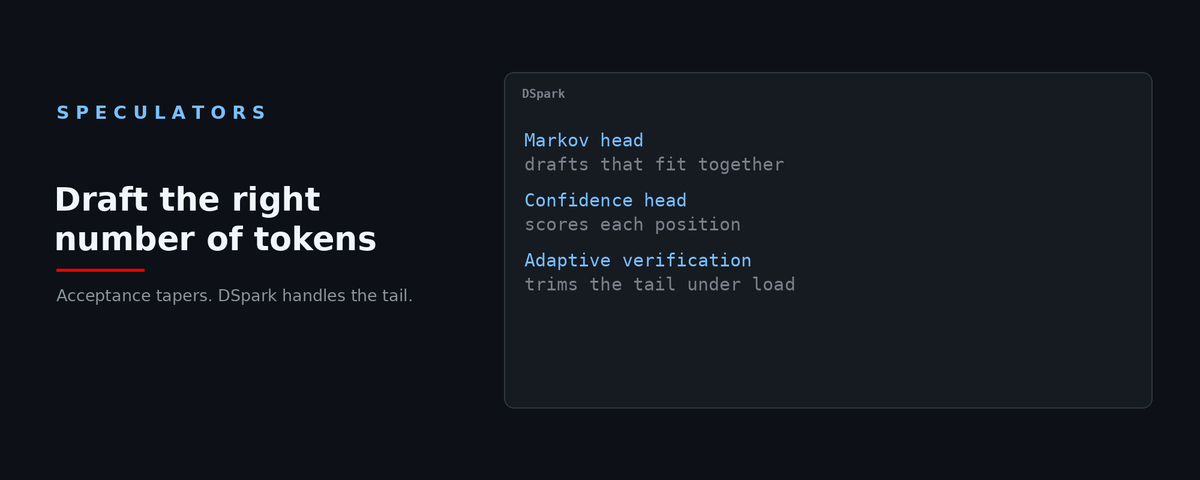
Meta's Muse Spark Open, 816B, runs on Red Hat AI Inference Server (preview). The detail worth knowing: its DSpark speculator drafts exactly 7 tokens, and there's a real reason it stops there. Suffix decay, explained:
Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Oct 19

Speculators v0.9.0 is out. Training got faster and lighter: a fused loss kernel gives up to 2x faster forward training passes on small (~1B) models, and an FP8 hidden-state backend cuts storage 50% while keeping speculator quality. Full notes: github.com/vllm-project/spec…

Post attachment
Sawyer Bowerman avatar
Sawyer Bowerman@_soyr_·Oct 19

Check out this recap on vLLM Office Hours #58!

Red Hat AI @RedHat_AI Oct 19 Article What the llm-d Semantic Classifier adds to your LLM routing stack A simple lookup and a multi-step proof don't need the same model. To route them differently, your gateway needs a useful signal before it chooses a destination. That's the problem behind the llm-d

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Oct 15

Two optimized checkpoints for NVIDIA Nemotron 3.5 Super VL, a 120B multimodal MoE for long-running agents. Quantization and speculative decoding stack for close to 2x on Hopper, accuracy intact. FP8 (LLM Compressor): huggingface.co/RedHatAI/NVID… DSpark (Speculators): huggingface.co/RedHatAI/NVID…

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 23

LLM Compressor v0.14.0 is out, and GPTQ just got its biggest speedup since launch. A new Triton kernel makes quantization ~15x faster end to end. Batching layers that share a shape pushes that to ~30x on some MoE workloads. Even the old eager path is 1.5-2x faster. Also new: expanded MSE/iMatrix observers that beat GPTQ for NVFP4 on internal benchmarks, REAP pruning with distributed DDP, and support for GLM 5.3 and Qwen3.8. Full release notes: github.com/vllm-project/llm-…

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 22

If your agent can act on real systems, with real credentials, over long time horizons, what actually stops it from doing the wrong thing? Not the prompt. The model is probabilistic; your operational controls can't be. @LegareKerrison kicks off AgentOps Unlocked series with the four gaps between a laptop demo and production: execution containment, identity, observability, and lifecycle governance. Built on open source you already know: Kubernetes, SPIFFE/SPIRE, OpenTelemetry. youtube.com/watch?v=LJHn6a_z…

Sawyer Bowerman avatar
Sawyer Bowerman@_soyr_·Sep 17

Using frontier LLMs for every agentic sub-task drains budget and increases latency. Check out how we look into picking more targeted models drives us to cost-effective, and "smart-enough" agentic execution. sprou.tt/1aZWuT9HcGQ

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 17

Kimi K3 is a 2.8T-parameter model. We trained a DSpark speculator for it, and the speedup holds up. Single-stream math reasoning goes from ~110 to ~435 tokens/sec per user. Under concurrent load, up to ~3.5x higher output throughput at matched interactivity. The drafter is a 5B model proposing 8 tokens a step, and on math it gets ~6.4 of them accepted per round. Training a drafter for a model this big meant going multi-node: Speculators plus a new Mooncake connector streaming hidden states between vLLM inference and training over RDMA. Two GB300 nodes to serve the target, one to train. vllm.ai/blog/2026-09-15-kimi…

Sawyer Bowerman avatar
Sawyer Bowerman@_soyr_·Sep 16

Super cool resrouce, fun to watch someone go through the whole process!

Everything you need to start self-hosting an open LLM. Run it on your own hardware. No API keys. No per-token bill. Nothing leaves your machine. The full path with @vllm_project: batch inference in Python, an OpenAI-compatible API server in one command, and quantized models that cut an 8B from ~16GB of weights to a quarter of that while keeping 98-100% accuracy. Walkthrough by @cedricclyburn.

10:56
Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 15

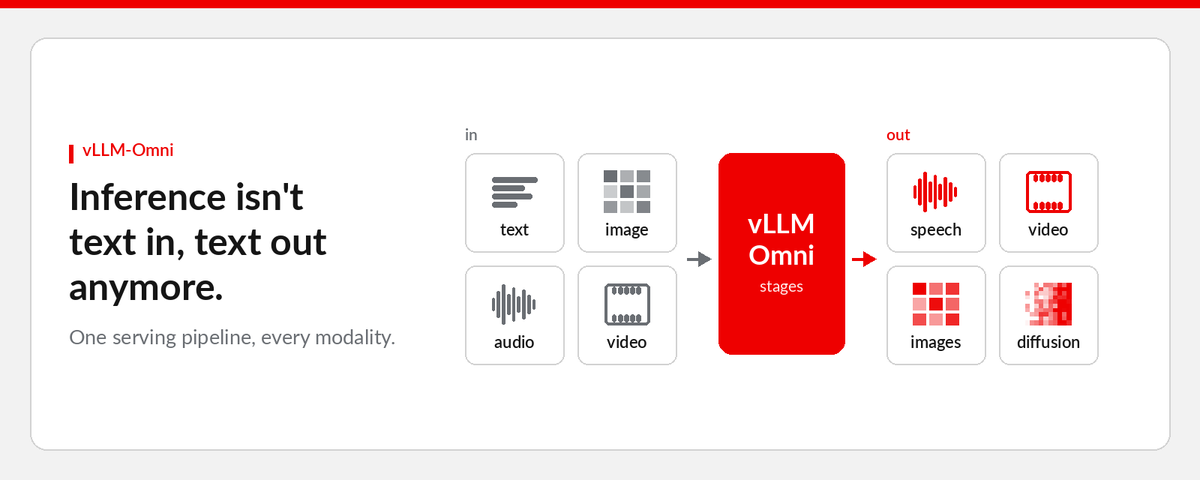
What does it take to serve a model that talks back, or one that generates video with audio? Most text models advance one token at a time. These don't, and they need different scheduling to match. New recap on how vLLM-Omni serves them:

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 10

Nothing over 33B parameters. That's the whole challenge. @NVIDIAAI and Red Hat are running an in-person Small Models Hack in Raleigh, October 17-18. Small, open models only. Build something that punches above its weight. Three tracks: 🎯 Fine-tune a small model to beat a general one at a real task 🕸️ Wire several small models into a multi-agent system 🛠️ Make one model call real tools reliably Brev credits provided to participants for GPU time all weekend. Prizes include an NVIDIA GeForce RTX 5090, NVIDIA Jetson Orin Nano Super Developer Kits, and more! 100 spots available: solo or up to teams of 3. Apply: luma.com/nvidia-redhat-small…

Red Hat Developer avatar
⟳ Sawyer Bowerman retweeted
Red Hat Developer@rhdevelopers·Sep 9

Tool calling is where agentic #AI demos fail in production. Discover why schema drift, unhandled execution errors, and non-deterministic tool outputs create the "last-mile problem," and how to build resilient execution interfaces on #OpenShift AI. ➡️ red.ht/4qXaHEw

Post attachment
Sawyer Bowerman avatar
Sawyer Bowerman@_soyr_·Sep 8

Surpass GPU memory ceilings in agentic workloads. Discover how vLLM's PagedAttention, prefix caching, and intelligent context pruning mitigate KV cache explosion during long-horizon autonomous reasoning loops. Thanks for taking some time to check it out! sprou.tt/1Tn9YSBX8H2

Red Hat AI avatar
⟳ Sawyer Bowerman retweeted
Red Hat AI@RedHat_AI·Sep 3

vLLM Office Hours today, 2pm ET: vLLM-Omni project update and live demos. A voice assistant on Qwen Omni, diffusion intermediate steps, and video generation. Plus what's new in vLLM 0.28 with @mgoin_. Get a recurring cal invite: red.ht/office-hours