
 Open web. Clear feed.

CTO @truvhq (acq by @checkr), PhD in ML&NLP
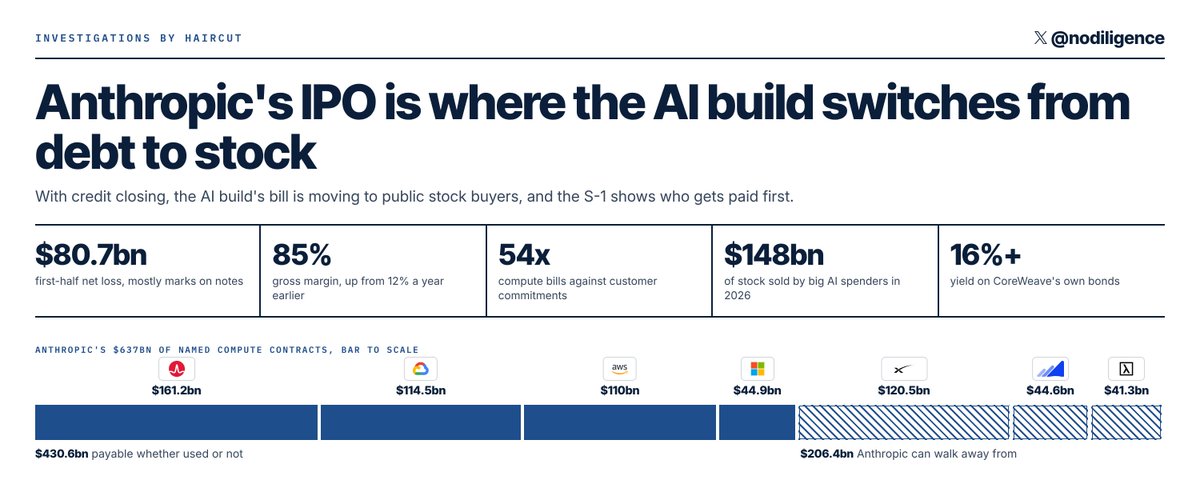
Best analysis of ANT IPO so far.
anthropic is probably the best business in AI right now and i still wouldn’t touch it on day one. the whole thing is set up for suppliers and insiders to sell into the index buying.
So intelligence got twice cheaper (and better) in about ~1 month?
🚀 DeepSeek-V4.1-Flash-1017 is here! Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API. 🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model. 1/4


Full details here chetvil.com/qwen-abliterated…

Internal models are available *weeks* before launch, not like some retards were suggesting that people inside live 2 generations of models above everyone else.
Some findings based on Anthropic’s published plot: - The share of merges on weekends rose steadily from 7% to 18% (+0.33 pts/week). Monday–Wednesday declined the most, Thursday slightly, and Friday held steady. - The time to double the number of daily merges shortened from 67 days (Jan – May) to 41 days (May – Jul) to 20 days (Aug – Sep) - Merge growth sped up about 5 weeks before Mythos Preview and Opus 4.7, and again before Opus 5.5 and Sonnet 5.5. That could mean the models were available internally weeks before launch.


If you ever wondered if Jev can improve coding performance of the models - it can't. Results are here chetvil.com/can-a-decision-m…

Full results of the local run are here: chetvil.com/deepseek-full-de…

It make sense to replace pretrain knowledge with RLed tool usage algos
Extrapolate this into any kind of LLM-produced result for which no human-made information exists, and you will get the percentage of time you are fooled by the LLM when working on something no one else has worked on.

I for one is happy that glm-5.3 is open source and everyone can learn adapt and harden their infrastructure, not whatever is anthropic trying to position here anthropic.com/research/glm-5…


