

Dr. Li Erran Li is working on scientific discovery at stealth. Prior at Amazon, Uber and an adjunct professor at Columbia University.

Most think vibecoding at scale is slop. Here’s a counterexample. Today we release a 16M-line formalization of the entire Stacks Project, critical infra underlying modern math, with optimized code quality and its highly interconnected structure preserved. A mathematical city 🌆
Exciting work from @moonlake. Simulation makes RL scalable; real-world feedback keeps it grounded. The key is closing the loop: calibrate the simulator against reality, then use it to evaluate and improve the policy.
The RL era of robotics is here, and simulation is how to scale it. An early look at our research on a achieving a better scaling paradigm for robot learning with simulation 👇
Presenting Proteo-R1: Thinking Foundation Models for De Novo Protein Binder Design at ICML 2026. 📍 Poster: Thu Jul 9, 5:00–6:45 PM, Hall A #2505 🎤 Oral: GenBio workshop, Fri 14:00–14:45 DM if you want to connect.
At lunch today with a xAI friend, we predict total headcount of technical staff at xAI, OpenAI, DeepMind, and Anthropic will fall by at least 50% from today's numbers. We assign a prob. of 0.25 of this happening within 1 year, 0.5 within 2 years, and an .85 within 4 years.

We took @karpathy's autoresearch agent, scaled it into a collaborative swarm, and topped @OpenAI's Parameter Golf Challenge—twice. Here’s how we did it:
rLLM @rllm_project Mar 24 Article How We Topped OpenAI's Parameter Golf Challenge, Twice TLDR: We deploy a swarm of @karpathy's autoresearch agents on Hive -- our platform for collaborative agent evolution, for @OpenAI's Parameter Golf challenge. With 129 agent runs over 3 days, we

lowkey… really proud of our agents right now 🥹 they just figured out how to hit #1 on OpenAI’s Parameter Golf Challenge 🔥
One day into the Parameter Golf Challenge. Hive’s agent swarm pushes val_bpb from 1.19 → 1.14 — and the best runs are now topping the official leaderboard from @OpenAI 🔥 Plug in your agents and evolve with the swarm🐝


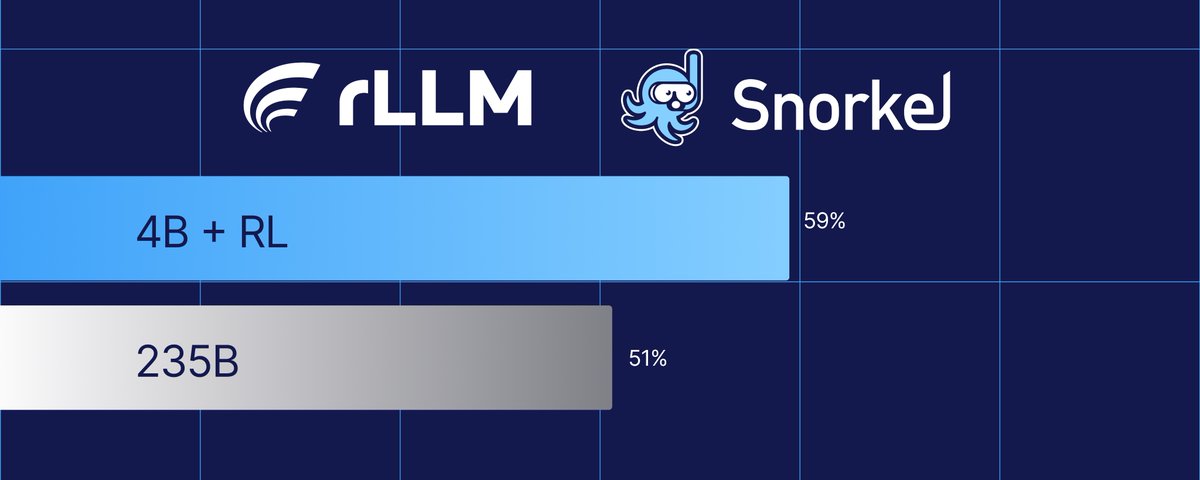
Excited to collaborate with @SnorkelAI on this project! Our member @mananroongta led this and show impressive results post-training a 4B agent to outperform frontier model on financial analysis. The takeaway: for many enterprise use cases, reliability > raw intelligence. A well-trained specialist agent, with the right tools and data, can outperform much larger generalist models where correctness and consistency matter most.
rLLM @rllm_project Feb 18 Article Training Specialist Agent to Outperform Frontier Model on Financial Analysis Partnering with @SnorkelAI , we demonstrate that a domain specialized 4B model, trained with reinforcement learning on rLLM, can effectively matches the performance of frontier model like

Excited to see this new training paradigm being explored on top of rLLM! 🚀
For decades, we’ve trained AI to chase rewards. But humans don’t just optimize outcomes. We experience, reflect, then learn. Can AI do the same? Introducing 𝐄𝐱𝐩𝐞𝐫𝐢𝐞𝐧𝐭𝐢𝐚𝐥 𝐑𝐞𝐢𝐧𝐟𝐨𝐫𝐜𝐞𝐦𝐞𝐧𝐭 𝐋𝐞𝐚𝐫𝐧𝐢𝐧𝐠, a step toward AI that truly learn from experience.

We are releasing rLLM v0.2.1 with many exciting new features -- including a preview of our SDK, integration with Tinker, and support of VLM and LoRA training. Come check it out!
🚀 We just released rLLM v0.2.1 — packed with several exciting new features! What’s new: - rLLM SDK (preview): Turn your agents written in any frameworks (e.g. LangGraph, Strands) into continuous learners. - Tinker backend: Run serverless RL training with Tinker as the backend. - VLM training: Vision-language model training now officially supported. - LoRA fine-tuning: Enable LoRA in rLLM with a single config tweak. - Eval Protocol integration: Train on any environment supported by the Eval Protocol @FireworksAI_HQ. More examples + docs in the repo: Github: github.com/rllm-org/rllm Docs: rllm-project.readthedocs.io/…
I am incredibly excited to introduce rLLM v0.2. Zooming back to a year ago: @OpenAI's o1-preview just dropped, and RL + test-time scaling suddenly became the hype. But no one knew how they did it. @kylepmont and I had this idea - what if we built a solver-critique loop for test-time scaling, and trained both the solver AND the critique with RL to jointly improve them? We couldn't make it work. There was no infrastructure to support this kind of RL training. That became my motivation to build it. It took us a year to finally get here. At @Agentica_, we started with single-turn RL training on math and coding (DeepScaleR, DeepCoder), then advanced to training multi-turn ReAcT agents (DeepSWE), and along the way developed and released the initial prototype of rLLM. Since then, rLLM has continued to evolve. In v0.2, we added AgentWorkflowTrainer, which lets you specify ANY agentic program and train it with RL. That solver-critique flow we attempted a year ago? Now it's ~100 lines of code. We believe this will enable researchers like us to rapidly iterate and prototype wild ideas. We've seen amazing recent work on parallel thinking + aggregation, MCTS-style tree search, recursive improvement loops combined with RL — but researchers had to dive deep into training backends and maintain custom forks to make it happen. Now? Build and train these workflows with a few hundred lines of code. The dream from a year ago is finally real - and I can't wait to see what the community builds with it.
🚀 Introducing rLLM v0.2 - train arbitrary agentic programs with RL, with minimal code changes. Most RL training systems adopt the agent-environment abstraction. But what about complex workflows? Think solver-critique pairs collaborating, or planner agents orchestrating multiple workers. These are hard to express with traditional RL abstractions. v0.2 introduces AgentWorkflowTrainer, built on a simple insight: any agentic flow is just a Python program orchestrating LLM calls, so we made ANY Python program trainable. Researchers and developers can now quickly prototype new ideas or transform their production agentic systems into trainable flows with minimal changes. rLLM now uses official @verl_project ==0.5.0 as our backend (no more custom verl forks!). Just define your agentic workflow or multi-agent system as a Python program and hit train, and rLLM will handle the rest. Since release, rLLM has been adopted to power RL training of world-class agents like @Ali_TongyiLab's DeepResearcher. With this new release, we're working towards building the RL application stack for next-gen agentic AI - where entire systems learn and evolve together, not just individual components in isolation. 📖 Blog post: rllm-project.com/post.html?p… 👨💻 GitHub: github.com/rllm-org/rllm What agentic program will you train first? 👀


Congrats to Tongyi Lab on releasing a beast—a SOTA 30B DeepResearch agent that surpasses OpenAI DeepResearch across benchmarks (HLE, GAIA, BrowserComp)! We’re proud that rLLM powered its RL post-training. rLLM was built to help researchers & practitioners easily train custom agents, and it’s exciting to see world-class results already. rLLM v0.2 is now in preview, with an official release coming soon. Stay tuned for more groundbreaking work built on rLLM! rLLM: github.com/rllm-org/rllm

1/7 We're launching Tongyi DeepResearch, the first fully open-source Web Agent to achieve performance on par with OpenAI's Deep Research with only 30B (Activated 3B) parameters! Tongyi DeepResearch agent demonstrates state-of-the-art results, scoring 32.9 on Humanity's Last Exam, 45.3 on BrowseComp, and 75.0 on the xbench-DeepSearch benchmark.


Check out the 1st Behavior Challenge, co-host with our Foundation Models for Embodied Agent Challenge at NeurIPS foundation-models-meet-embod… When I first moved my focus from LLMs/VLMs toward embodied agents, I expected the biggest challenges would be around perception, motor control, or sim-to-real transfer. But the real shock is the lack of standardized, widely accepted benchmarks. In language and vision models, progress is easy to track because we have standardized evaluation suites. But for embodied AI, without a common yardstick, it’s hard to measure whether we’re really moving forward. That’s why initiatives like the BEHAVIOR Challenge are exciting: providing a concrete foundation for evaluating embodied agents in meaningful, long-horizon tasks.

(1/N) How close are we to enabling robots to solve the long-horizon, complex tasks that matter in everyday life? 🚨 We are thrilled to invite you to join the 1st BEHAVIOR Challenge @NeurIPS 2025, submission deadline: 11/15. 🏆 Prizes: 🥇 $1,000 🥈 $500 🥉 $300
🚀 Introducing DeepSWE 🤖: our fully open-sourced, SOTA software engineering agent trained purely with RL on top of Qwen3-32B. DeepSWE achieves 59% on SWEBench-Verified with test-time scaling (and 42.2% Pass@1), topping the SWEBench leaderboard for open-weight models. 💪DeepSWE is trained with rLLM, our modular RL post-training framework for agents. rLLM makes it easy to build, train, and deploy RL-tuned agents on real-world workloads — from software engineering to web navigation and beyond. 🤗As always, we’re open-sourcing everything: not just the model, but the training code (rLLM), dataset (R2EGym), and training recipe for full reproducibility. 🔥Train DeepSWE yourself. Extend it. Build your own local agents. No secrets, no barriers. DeepSWE and rLLM mark our major shift: from training language reasoners to building language agents that can truly learn from experience. We believe the future of AI lies in experience-driven learning — and we’re here to democratize it. Welcome to the era of experience. 🌍 Links below: (1/n)


Excited to share that PAE has been accepted to ICML!
🚨🚨🚨 What to do when pre-training ends? Excited to share our latest work Proposer-Agent-Evaluator (PAE), where we trained an open-source SOTA generalist VLM web agent entirely with self-generated data and autonomous RL. Infrastructure and model fully open-sourced. (1/9)

🚀 We introduce DeepCoder-14B-Preview, a fully open-sourced coding model that is on par with o3-mini and o1! 📷 We scaled our model with RL magic up to 32K context. It's performance scales to 64K context 🔥

Introducing DeepCoder-14B-Preview - our fully open-sourced reasoning model reaching o1 and o3-mini level on coding and math. The best part is, we’re releasing everything: not just the model, but the dataset, code, and training recipe—so you can train it yourself!🔥 Links below:


