
 Open web. Clear feed.

Enterprise AI - AI agents harness - Local LLMs
1/8 Looped transformers are coming. OpenMythos, recurrent-depth architectures, weight recycling — the frontier labs are all exploring this. But here's what nobody's talking about: the hardware implications are massive. Let me break it down. 🧵
Introducing OpenMythos An open-source, first-principles theoretical reconstruction of Claude Mythos, implemented in PyTorch. The architecture instantiates a looped transformer with a Mixture-of-Experts (MoE) routing mechanism, enabling iterative depth via weight sharing and conditional computation across experts. My implementation explores the hypothesis that recursive application of a fixed parameterized block, coupled with sparse expert activation, can yield improved efficiency–performance tradeoffs and emergent multi-step reasoning. Learn more ⬇️🧵

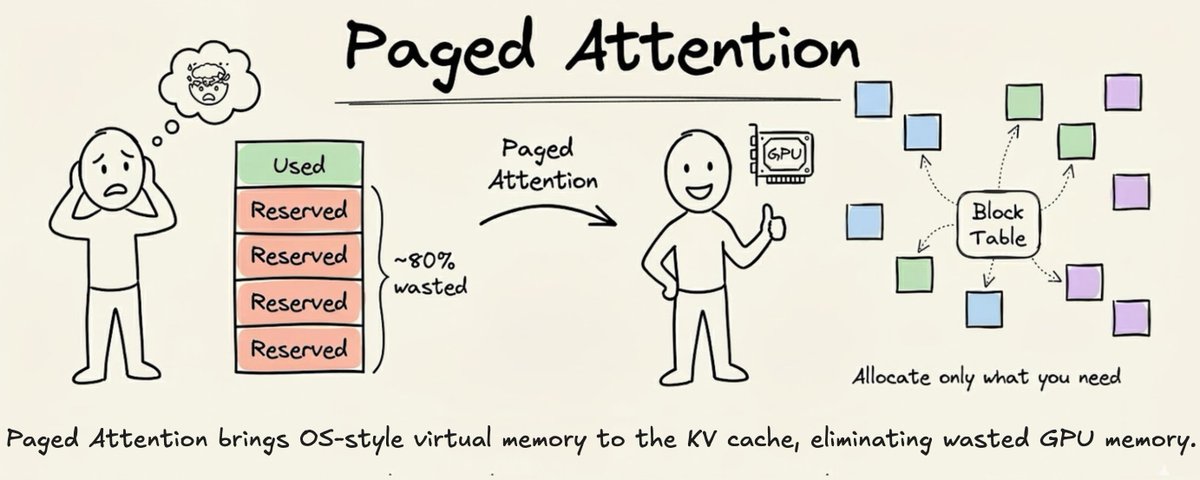
This is how vLLM got started. The best explanation by far!
Avi Chawla @_avichawla Mar 11 Article Paged Attention in LLMs, clearly explained! When you’re serving LLMs at scale, memory becomes your bottleneck before compute does. The problem isn’t a lack of GPU memory; it’s how inefficiently we use it. Let’s understand why this happens and
Such a big deal. Alternatives are @UnslothAI and @axolotl_ai
Introducing Trellis for Kimi K2 Thinking. It's post-training code that's 50x faster than the best single-node open-source version and 2x cheaper than training APIs. After safety testing, we're open-sourcing it, giving builders the best tools to customize a frontier model. 🧵

Curious to see whether they will release medium-size models to compete with Alibaba Qwen3.5 series
Finally, V4 is coming * Set to release next week ahead of the Two Sessions * Optimised for Chinese chips led by Huawei and Cambricon * Multi-modal and early tests results are “impressive” Exclusive: DeepSeek to release long-awaited AI model as.ft.com/r/cd6577d9-0633-49…


