So excited to finally share what our team has been building! 🚀
Meet Gemini 3.8 Flash and Gemini 3.8 Flash Cyber:
⚡Massive leaps in long-horizon coding & agentic tasks
🛡️Frontier-level automated vulnerability detection & patching with Flash speed/pricing
Introducing Gemini 3.8, our best reasoning & coding model yet.
By leveraging long-running agentic loops, we’re building on the momentum of 3.7 Flash from just three weeks ago to release two new 3.8 variants:
Meet Gemini 3.8 Flash and Gemini 3.8 Flash Cyber 🧵
Wonder is here, and it's looking Wonder Full! 🍉
We've worked hard to push its intelligence and real-world usefulness, especially for coding, agentic and personal superintelligence.
Proud to be part of this journey. More wonders ahead!
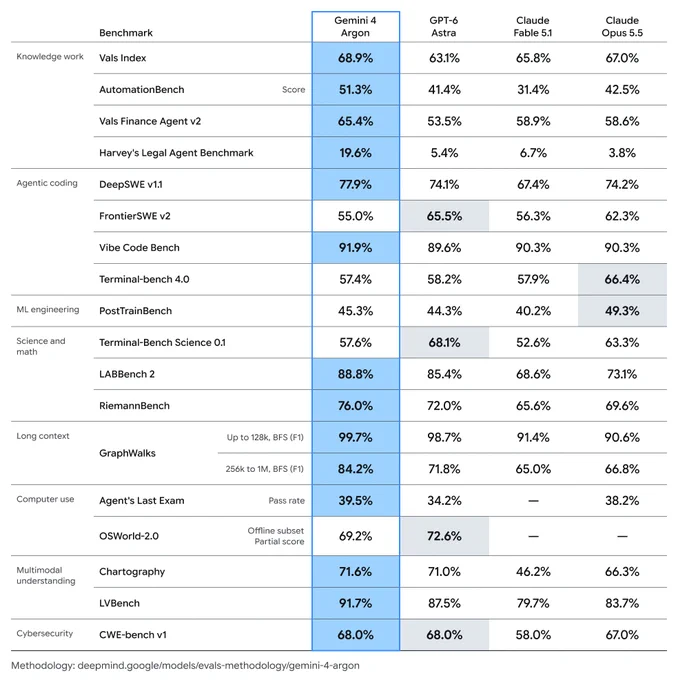
Today, we announced Gemini 4 Argon, our next generation model and a cybersecurity powerhouse equipping defenders for the next era of cyberattack.
On the Gray Swan IPI Benchmark, Gemini 4 Argon leads in prompt injection robustness. @GoogleDeepMind
Excited to bring Gemini 4 Argon! Incredibly strong across general reasoning, agents, coding, and cybersecurity.
Great time to be working on cyber defense and turning frontier capabilities into real-world vulnerability discovery and remediation. 🚀
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Today we’re launching Gemini 3.8 Flash Cyber and Gemini 3.8 Flash. ⚡️🛡️
3.8 Flash Cyber is our most capable cybersecurity model for finding and fixing vulnerabilities. It sits on the Pareto Frontier on CWE-Bench for patching. Available to trusted defenders through our new Fairwind Program.
Introducing Gemini 3.8 Flash, another upgrade in under a month! And the new 3.8 Flash Cyber pushes the frontier of cyber defense. Relentless progress 🚀 More on the models & our cyber security work in the blog - happy building! blog.google/innovation-and-a…
Introducing Gemini 3.8 Flash, another jump in Gemini's agentic + coding capabilities, and our 3rd updated Flash model in only 6 weeks...
This model has been a ton of fun to work with, excited to see what you all think!
Excited to announce Gemini 3.8 Flash and 3.8 Flash Cyber @googleblog.google/innovation-and-a…
Our cyber model has frontier capabilities being competitive on finding and patching benchmarks with much larger models, at a cheaper cost.
@GoogleDeepMind
Muse Spark 1.2 and MuseCode are out—less than a month after Muse Spark 1.1! 🚀
Excited to join the journey and see the pace of progress. Give it a try and let us know what you build!
curl -fsS dev.meta.ai/install.sh | bash
muse code in beta is live. first coding agent from msl, built on muse spark 1.2.
install: curl -fsS dev.meta.ai/install.sh | bash
here's what you should know:
Muse Spark 1.1 🥑 is out! with lot of improvements on agents / reasoning / coding.
Scaling RL has been tiring, rewarding, and full of lessons.
Try it on dev.meta.ai and please send feedback + failure cases. They help make the model better.
More to come!
1/ muse spark 1.1 is an industry-competitive agentic and coding model. across many agentic evals it rivals gpt-5.5 and opus-4.8.
available now through the new meta model api and in meta ai. 🧵
Excited to be at #NeurIPS through Dec 8 — happy to connect!
I’ll be presenting our Spotlight paper on complex QA and reasoning with search:
🗓️ Dec 5, 11:00–2:00pm PST
📍 Exhibit C/D/E — Poster #1908
Also exploring full-time opportunities—DMs open if you’d like to chat!
4. TIR-Judge
Google and collaborators introduce TIR-Judge, an end-to-end reinforcement learning framework that trains LLM judges to integrate code execution for precise evaluation.
New Google paper trains LLM judges to use small bits of code alongside reasoning, so their decisions become precise.
So judging stops being guesswork and becomes checkable.
Text only judges often miscount, miss structure rules, or accept shaky logic that a simple program would catch.
TIR-Judge makes the judge think step by step, write code to check claims, run it in a sandbox, then update the verdict.
Training mixes tasks where code can verify answers and tasks where it cannot, so the judge learns when to call tools and when to rely on reasoning.
One prompt schema covers pointwise scoring, pairwise choices, and listwise selection, so it plugs into many workflows.
Reinforcement learning rewards being correct, following strict output tags, and using at most 3 tool calls.
A variant called TIR-Judge-Zero skips teacher distillation and still improves by alternating reinforcement learning, rejection sampling, and supervised fine tuning.
Across public judge benchmarks it beats text only judges, and with 8B it reaches 96% of Claude Opus 4 on listwise ranking.
The core idea, give the judge verifiable checks plus rewards that favor careful tool use.
----
Paper – arxiv. org/abs/2510.23038
Paper Title: "Incentivizing Agentic Reasoning in LLM Judges via Tool-Integrated Reinforcement Learning"
7/n
Thanks to my collaborators:
Jingjing Chen
Jiayu Ye
Yu Wu
Jun Yan @jun_yannn
Carl Yang @yangji9181
Hongkun Yu
And thanks for the useful discussions from:
Jing Nathan Yan @NathanYan2012
Yuchen Zhuang @yuchen_zhuang
Zhengzhe Yang
6/n
📊Best-of-N on Policy Models
TIR-Judge is not only a better judge — it makes other models better.
When selecting responses in best-of-N inference, TIR-Judge improves policy accuracy by +3.9~6.7% on AIME, BigCodeBench, IFEval, etc.
→ Better downstream reasoning too🎯
4/n
🧬 Two variants
🔹 TIR-Judge-Distill: starts from Gemini-2.5-Flash-Tool
🔹 TIR-Judge-Zero: trained from initial checkpoint via iterative RL
→ Zero matches or surpasses Distill — RL alone can teach tool-use! 🤯